




AI in Tribology
Introduction
Artificial intelligence (AI) is opening new possibilities for tribology research, from predicting friction and wear behaviour to accelerating complex simulations and improving engineering education. However, successfully applying AI to tribology requires more than sophisticated algorithms. Reliable data, physical understanding, and appropriate modelling techniques are equally important.
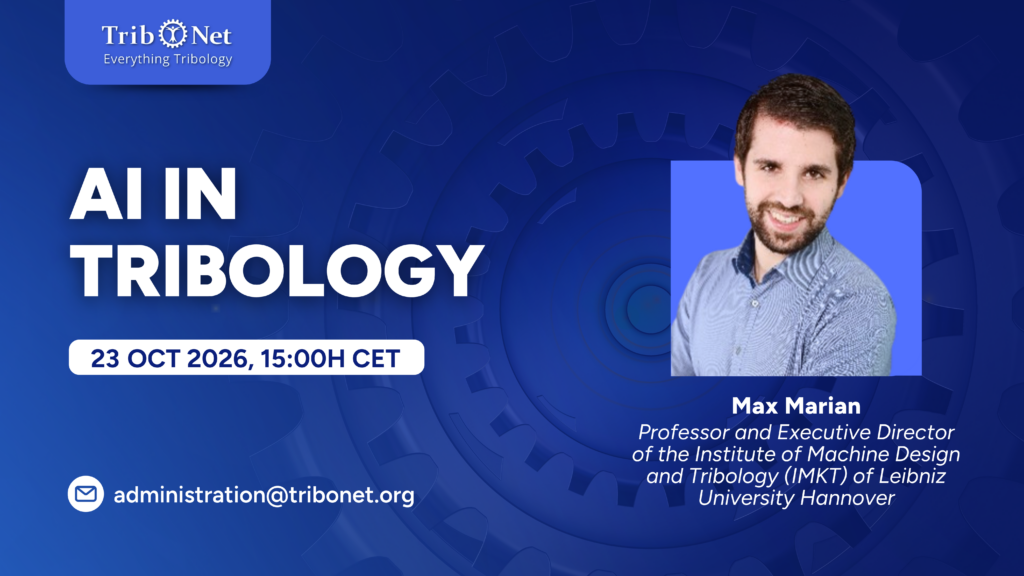
These topics were explored during TriboNet’s webinar, AI in Tribology, held on October 23, 2026. The session was presented by Professor Max Marian, Head of the Institute of Machine Design and Tribology at Leibniz University Hannover, Germany.
Drawing on his research in machine learning, contact mechanics, and lubrication, Marian discussed how AI can support tribological research through data-driven prediction, hybrid modelling, and physics-informed neural networks. The webinar also examined the role of AI in education, demonstrating how intelligent tools can make technical knowledge more accessible to students. A central message emerged throughout the presentation: the future of AI in tribology depends on combining high-quality data, machine learning, and physical knowledge rather than relying on data alone.
Why Is Artificial Intelligence Important in Tribology?
Tribology is the science of friction, wear, and lubrication. These phenomena influence the performance, efficiency, reliability, and service life of components such as bearings, gears, seals, and other mechanical systems.
Traditionally, tribological knowledge has been developed through a combination of experiments, theoretical models, and numerical simulations. Researchers design experiments, measure relevant parameters, analyse the results, and use their findings to guide further investigations.
Although these approaches remain essential, modern tribology research increasingly involves complex systems, multiple interacting physical phenomena, and large volumes of information. Experimental measurements, surface characterisation, numerical simulations, and operational monitoring can all generate valuable data, but extracting meaningful relationships from these sources can be challenging.
AI and machine learning offer additional ways to analyse this information. They can identify patterns, classify system conditions, predict physical responses, and help researchers explore a wider range of operating parameters. As discussed in TriboNet’s article on the Need for AI in Tribology, AI has potential applications in condition monitoring, fault diagnosis, material selection, and the prediction of tribological behaviour.
However, AI does not automatically provide a physical explanation for every pattern it identifies. Its predictions depend on the quality of the available data, the suitability of the model, and the conditions represented during training. This makes data preparation and physical understanding fundamental to developing reliable AI applications in tribology.
FAIR Data: Building the Foundation for Reliable AI
One of the main topics of the webinar was the importance of data management. Before researchers can effectively train machine learning models, their data must be organised, documented, and accessible in a form that both people and machines can understand.
Marian explained that research institutions often generate heterogeneous datasets using different experimental procedures, measurement devices, software, and documentation practices. Individual researchers may also store their results separately, making it difficult to combine information across projects.
Without sufficient context, researchers may struggle to reproduce earlier experiments, compare results from different studies, or identify relationships between variables. The same problems can prevent AI systems from interpreting and reusing the data correctly. To address these challenges, the webinar introduced the FAIR data principles:
- Findable: Data should be identifiable and discoverable through persistent identifiers and descriptive metadata.
- Accessible: Data should be retrievable through clearly defined access procedures.
- Interoperable: Data should use consistent formats, terminology, units, and structures that allow different systems to work together.
- Reusable: Data should include sufficient documentation, provenance, licensing information, and methodological context for future use.
An important distinction is that FAIR data does not necessarily have to be publicly available. Access can be restricted when necessary, provided the relevant access conditions are clearly defined.
For tribology, FAIR data can include experimental measurements, lubricant properties, surface characterisation results, operating conditions, and simulation outputs. Connecting these elements allows researchers to understand not only the numerical results but also the circumstances under which they were obtained.
Marian described work at his institute to develop structured datasets and glossaries, including published research data relating to rolling bearings and wear under dry-lubricated conditions. These efforts demonstrate how standardised terminology and documented datasets can support future research and machine learning applications.
The webinar also highlighted the potential of knowledge graphs. Rather than treating every dataset as an isolated file, a knowledge graph connects related information through defined relationships. For example, it could link a material sample to its processing history, experimental conditions, measured friction, and observed wear.
These connections could eventually help researchers move from isolated datasets towards shared scientific knowledge across institutions and research communities. For additional context, TriboNet’s webinar on Findable AI-Ready (FAIR) Data in Tribology explores why structured data and knowledge graphs are important for scaling AI in engineering research.
Data-Driven Machine Learning for Condition Monitoring
After discussing data preparation, Marian presented examples of data-driven machine learning in tribology. These approaches learn relationships from existing data rather than explicitly solving all the physical equations governing a system.
One example involved condition monitoring and fault diagnosis in a mechanical friction clutch. Researchers investigated different clutch conditions, including healthy components and systems with damaged friction materials or broken components.
An accelerometer was used to collect vibration measurements under different loading conditions. The researchers then extracted features from the recorded signals and applied machine learning algorithms to classify the system’s condition. The methods included decision trees, support vector machines, k-nearest neighbours, random forests, and neural networks.
The results demonstrated that model performance depends on both the selected algorithm and the features used for training. An algorithm that performs well under one loading condition may not be the best choice under another.

This is an important consideration for practical applications. Mechanical systems rarely operate under identical conditions at all times, so a model trained on a limited range of operating states may not generalise reliably.
Marian also discussed ensemble learning, in which multiple machine learning models are combined to improve prediction performance. Instead of relying on a single classifier, an ensemble can combine the predictions of several models using methods such as majority voting. The presentation illustrated how this strategy can improve fault classification compared with individual models in the investigated cases.
Another example involved deep learning for the classification of wear particles in scanning electron microscope (SEM) images. Pre-trained convolutional neural networks were adapted to recognise features in the new dataset, and combining different models into an ensemble provided another way to improve classification performance.
Together, these examples showed that machine learning can support different types of tribological analysis, from vibration-based fault diagnosis to image-based wear assessment. They also emphasised the importance of selecting and evaluating models according to the specific problem.
Accelerating Elastohydrodynamic Lubrication Simulations with AI
A major part of the webinar focused on elastohydrodynamic lubrication (EHL), particularly the challenge of predicting pressure and lubricant film thickness in rolling contacts. EHL occurs when the pressure generated in a lubricated contact is high enough to produce significant elastic deformation of the contacting surfaces. The lubricant’s properties also change under pressure, influencing the formation and behaviour of the lubricating film.
Understanding these effects is important for predicting friction, evaluating lubrication performance, and assessing the operating conditions of components such as rolling bearings and gears.
Traditional approaches include analytical equations and numerical methods, such as finite element methods (FEM). Analytical equations can provide rapid estimates but have limitations in their range of validity. More detailed numerical simulations can capture complex physical behaviour, although they require more computational resources.
Marian illustrated this challenge using rolling-bearing simulations. Modelling a bearing can involve many individual contact regions, each requiring calculations under its respective loading conditions. When multiple bearings and gears are included in a complete drive system, the total computational cost can become substantial.

To address this issue, his research team developed a machine learning approach to predict EHL contact behaviour. The team generated approximately 45,000 data points using detailed numerical simulations. The resulting pressure and film thickness distributions were then used to train an artificial neural network.
Unlike models that predict only a single value, such as minimum film thickness, this network was designed to predict the distributions of pressure and film thickness across the contact.
According to the results presented during the webinar, the neural network predictions closely matched the numerical solutions for the representative test cases. Marian reported that a numerical solution could take around 30 seconds for an example case, whereas the neural network prediction took approximately two milliseconds. This difference illustrates the potential of machine learning as a fast surrogate model for computationally expensive simulations.
The predicted distributions can also be used to calculate other quantities, including rolling traction, sliding-related friction, and electrical capacitance-related parameters. This makes the approach potentially useful for applications that require repeated calculations across many operating conditions. Further information about the underlying physical principles can be found in TriboNet’s guide to Elastohydrodynamic Lubrication (EHL).
Challenges and Future Opportunities
Despite its potential, AI adoption in tribology still faces several challenges. First, data quality and standardisation remain essential. Inconsistent terminology, missing metadata, incompatible units, and insufficient experimental documentation can limit the reliability of machine learning models.
Second, model performance must be evaluated across different operating conditions. As demonstrated in the webinar’s condition-monitoring example, no single algorithm necessarily performs best in every situation.
Third, physics-informed and hybrid approaches require careful implementation. Incorporating physical equations can improve the structure of a model, but the training process and numerical behaviour still need to be assessed.
Finally, researchers must determine when AI provides a meaningful advantage over existing methods. In some situations, a simple analytical equation may be sufficient. In others, a machine learning surrogate or hybrid numerical approach may offer substantial benefits.
The webinar also discussed potential applications in surface texturing and optimisation. Marian explained that AI-based surrogate models can help explore different texture geometries and support optimisation, particularly when the relevant physical behaviour can be modelled numerically. Dry contacts can be more challenging because additional physical and chemical effects may need to be considered.
These examples reinforce the importance of choosing an approach that reflects the specific tribological system rather than treating AI as a universal solution.
Conclusion
TriboNet’s AI in Tribology webinar presented a broad overview of how artificial intelligence and machine learning can support modern tribological research and education. From FAIR data and condition monitoring to EHL prediction, hybrid modelling, and physics-informed neural networks, the examples demonstrated several ways AI can help researchers analyse complex systems and reduce computational demands.
The session also highlighted the importance of preparing reliable, reusable data and maintaining a strong connection between machine learning and physical understanding. AI can accelerate predictions and support knowledge discovery, but its effectiveness depends on the quality of the data, the suitability of the model, and the validity of the underlying assumptions.
As research progresses, combining data-driven methods with established physical models could help make tribological simulations more efficient, improve condition monitoring, and support new approaches to engineering education.
Ultimately, the future of AI in tribology is not simply about building more powerful algorithms. It is about creating a reliable connection between data, physics, and engineering expertise to advance the understanding of friction, wear, and lubrication.
0 Comment