




AI-Ready Tribology Data: How to Prepare Friction and Wear Curves for Machine Learning
By Aydar Akchurin
Tribology has no shortage of data. Laboratories generate friction curves, wear scars, surface maps, lubricant analyses, microscopy images, acoustic signals and temperature histories every day. The problem is that much of this data is difficult for humans to compare and even harder for machine-learning systems to use.
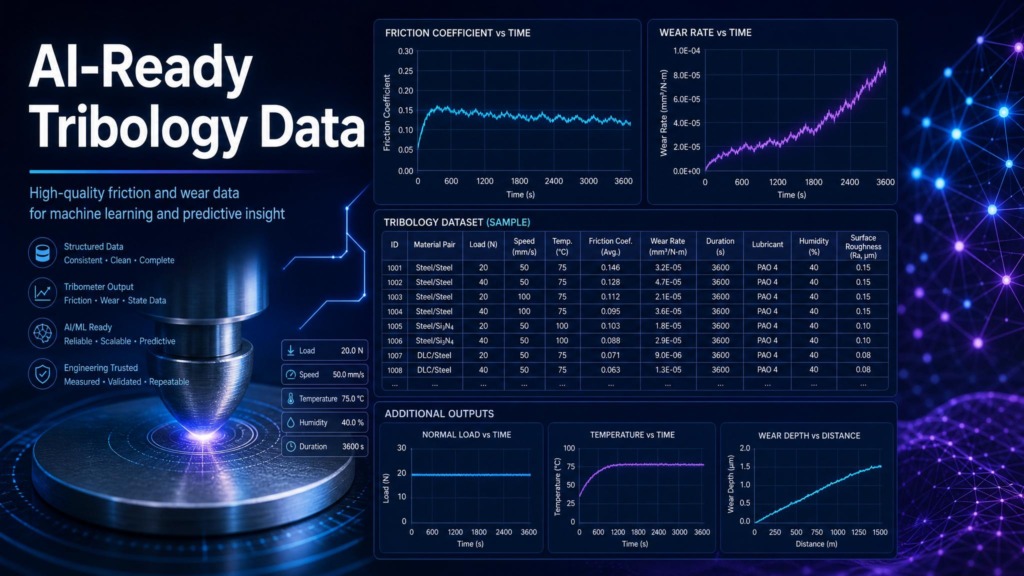
AI-ready tribology data is not just a CSV file with a friction column. It is a structured package of raw signals, processed results, metadata, units, test context, uncertainty and surface evidence. Without that context, a model can learn correlations that look impressive but fail when moved to a new machine, material pair or lubricant chemistry.
What “AI-ready” means in tribology
AI-ready data is data that can be found, understood, checked and reused by people and software. In tribology, that is harder than in many fields because test results are highly system-dependent. The same material pair can produce different friction and wear behavior when the contact geometry, stiffness, surface finish, lubricant supply or environment changes.

AI-ready does not mean overcomplicated. It means the dataset includes enough structure for another engineer — or a model — to understand what was tested and whether comparisons are valid.
For foundation concepts, see TriboNet’s pages on friction, wear, tribology and boundary lubrication.
The minimum useful data package
| Data layer | Examples | Why it matters for AI |
|---|---|---|
| Raw signals | time, friction force, normal force, position, speed, temperature, voltage/current if relevant | Allows reprocessing, feature extraction and error checks |
| Processed outputs | COF, wear volume, wear rate, steady-state average, slope, uncertainty | Gives target variables and engineering summaries |
| Metadata | materials, geometry, roughness, lubricant, load, speed, environment, instrument | Prevents false comparisons between different systems |
| Surface evidence | wear scar images, profilometry, microscopy, debris, chemistry | Connects numbers to mechanisms |
| Quality notes | calibration, filtering, excluded cycles, anomalies, repeats | Helps models avoid learning artifacts |
Why final averages are not enough
A single average coefficient of friction can hide running-in, stick–slip, lubricant starvation, surface failure, direction asymmetry, temperature drift and machine dynamics. For machine learning, that is dangerous because two curves with the same average may represent completely different mechanisms.
Instead of storing only one number, keep the curve and label important regions:

- running-in: early surface adaptation, transfer-film formation or smoothing;
- steady-state: the region used for comparable average friction or wear-rate calculation;
- transition: changes caused by temperature, film breakdown, additive activation or debris;
- failure/end-of-life: scuffing, coating breakthrough, seizure, unstable friction or rapid wear.
These regions can become features for machine learning, but they are also useful for ordinary engineering review.
Related TriboNet webinar: Findable AI-Ready (FAIR) Data in Tribology discusses why structured data, knowledge graphs and FAIR principles matter for scaling AI in tribology. TriboNet also lists upcoming AI-focused webinars including TriboAI: Making Language Models Read Friction Curves and AI in Tribology.
Recommended columns for friction curves
For a sliding or reciprocating tribology test, a useful raw-data file might include:
- time_s
- cycle_number
- normal_force_N
- friction_force_N
- coefficient_of_friction
- position_mm or angle_deg
- sliding_speed_mm_s
- stroke_direction, if reciprocating
- temperature_C
- humidity_percent, if relevant
- electrical_voltage_V and current_A, if electrified
- event_label, such as running_in, steady_state, transition or failure
Use plain, consistent column names. Include units in the column name or in a separate schema file. Avoid ambiguous columns such as “force1” or “value.” Future-you will not remember what they meant, and an AI system definitely will not.
Metadata that should travel with the data
Tribology metadata is not administrative clutter. It is what makes the dataset scientifically usable. Include:
- test method, standard and instrument model;
- contact geometry and dimensions;
- materials, coatings, heat treatment, hardness and supplier/batch if available;
- surface roughness and preparation method;
- lubricant name, viscosity, additives, aging state and supply method;
- load, speed, stroke, duration, sliding distance and temperature;
- environment: humidity, atmosphere, contamination, water content;
- calibration date and sensor ranges;
- filtering, smoothing, averaging and excluded data rules;
- repeat count and reason for any failed or removed tests.
Preparing wear data for machine learning
Wear data is especially easy to damage with poor reporting. A wear rate without measurement method, density, scar geometry, uncertainty and surface evidence is hard to reuse.
For each wear result, store:
- wear volume or mass loss and the measurement method;
- specific wear rate formula and units;
- sliding distance, normal load and test duration;
- wear scar images and profilometry files where possible;
- dominant wear mechanism label: adhesive, abrasive, oxidative, fatigue, tribocorrosion, etc.;
- uncertainty or scatter across repeats.
Quality checks before training a model
- Check unit consistency across all files.
- Plot every friction curve before feature extraction.
- Flag tests with sensor saturation, lost contact, obvious drift or interrupted runs.
- Separate machine artifacts from contact behavior when possible.
- Do not mix different geometries or materials without metadata labels.
- Keep training, validation and test sets separated by material family or test campaign when evaluating generalization.
- Preserve raw files even after generating cleaned datasets.
FAIR principles in plain engineering language
FAIR means data should be Findable, Accessible, Interoperable and Reusable. For a tribology lab, that can be translated into simple habits:
- Findable: use stable file names, project IDs and searchable metadata.
- Accessible: store data in shared, documented locations rather than scattered personal folders.
- Interoperable: use standard formats such as CSV, JSON, HDF5, TIFF or vendor exports with conversion notes.
- Reusable: include units, methods, calibration, uncertainty and surface evidence.
FAQ
What is AI-ready tribology data?
AI-ready tribology data is structured, documented and machine-readable data that includes raw signals, processed results, metadata, units, uncertainty and evidence needed to interpret friction and wear behavior.
Can machine learning use average coefficient of friction?
It can, but average COF alone is usually weak. Raw curves and curve features are more useful because they preserve running-in, instability, transitions and failure behavior.
What format should tribology data use?
CSV is useful for simple time series. JSON or YAML can store metadata. HDF5 can combine larger structured datasets. The key is consistency, units and documentation.
Why is metadata so important in tribology?
Friction and wear are system responses. Load, speed, geometry, surface roughness, lubricant, environment and machine dynamics can all change the result, so metadata defines what the numbers mean.
Should failed tests be deleted from AI datasets?
No. Failed or anomalous tests should usually be flagged, not deleted. They may be useful for failure prediction or quality control, but models need to know why they are different.
How should friction curves be labeled?
Useful labels include running-in, steady-state, transition, failure, direction, temperature step, lubricant change and any known anomaly such as vibration, loss of contact or sensor saturation.
Takeaway
AI will not fix poorly structured tribology data. It will amplify whatever structure, bias and missing context already exist. The best starting point is not a complicated algorithm; it is disciplined data packaging.
Keep the raw curves, document the test, label the curve regions, attach surface evidence and report uncertainty. Then machine learning has a chance to learn tribology rather than lab habits.
0 Comment